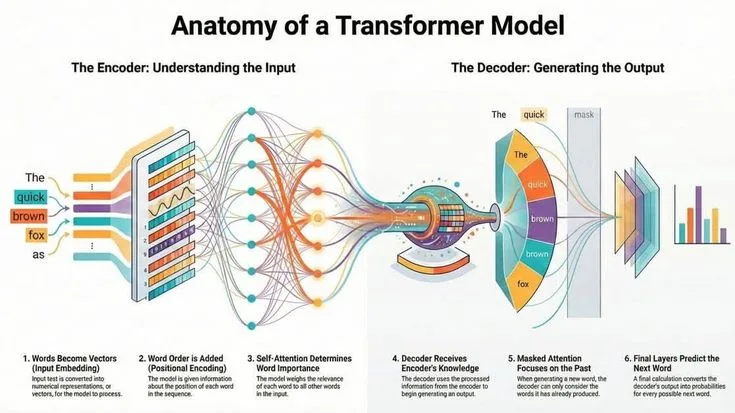
Understanding Transformer Architecture in AI
This is the CitePep accuracy record for “Understanding Transformer Architecture in AI”, published by When Notes Fly. It lists every change experts checked and accepted on that page.
Transformer architecture is the backbone of modern AI, facilitating advanced language processing.
What has been corrected on this page?
Every accepted correction to this page is recorded with the exact change, so readers can see how the page improved over time.
-
Sparse Transformer (Child et al., 2019) reduces attention complexity to O(N*sqrt(N)), not O(N log N).
Beforereducing complexity from O(N^2) to O(N log N)
Afterreducing complexity from O(N^2) to O(Nu221AN)
Why: Sparse Transformer (Child et al., 2019) reduces attention complexity to O(N*sqrt(N)), not O(N log N). Verified fix already live in body; no leftover instances found in faq/excerpt/meta.
View the full record →
Who checked this page?
1 contributor has checked "Understanding Transformer Architecture in AI" on When Notes Fly. Each name below links to that person's public CitePep profile, where every contribution they have made is listed with the exact change they proposed.